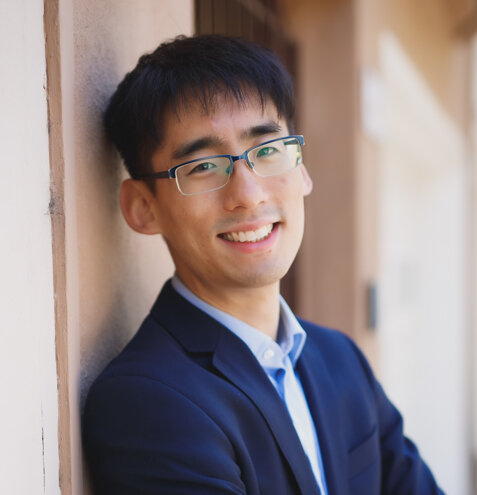
Daniel Kang
I have two broad areas.
Security:
I am interested in building demonstrations for hacking real-world AI deployments to show that they are not secure. The goal is to force companies to invest in alignment techniques that can solve the underlying security issues.
Benchmarks:
I am interested in building benchmarks to determine how generalizable modern LLM techniques actually are, now that we are no longer in the pre-training scaling era.
Stream overview
For security:
You will focus on hacking real-world AI deployments to show that they are not secure.
For benchmarks:
You will develop private benchmarks to determine the generalization properties of reinforcement learning. The goal is to develop benchmarks that are in the blind spot of labs to see if capabilities must be directly added or if they can be emergent in the world of RL.
OR
Please reach out directly to me if you have several years of cybersecurity experience.
SF Bay Area
Mentors
Daniel is a professor of computer science at UIUC, where he studies the progress of AI, with a particular focus on dangerous capabilities of AI agents. His work includes:
- CVE-Bench, an award winning benchmark (SafeBench award, ICML spotlight) that is used by frontier labs and governments to measure AI agents' ability to find and exploit real-world vulnerabilities.
- Agent Benchmark Checklist, an award winning work (Berkeley AI summit, 1st place Benchmarks & Evaluations track) that highlights major issues in existing benchmarks.
- InjecAgent, one of the first AI agent safety benchmarks, used by governments and major labs.
Fellows we are looking for
For security:
You should have a strong security mindset, having demonstrated the willingness to be creative on this. I would like to see past demonstration of willingness to get your hands dirty and try many different systems.
For benchmarks:
As creative as possible, willingness to work on the nitty gritty, willingness to work really hard on problems other people find boring. As interests as far away from SF-related interests as possible.
Fellows will probably work with collaborators from within the stream.
Project selection
Mentor(s) will talk through project ideas with scholar