MATS 导师正在拓展 AI 对齐、透明度和安全研究的前沿









Ryan 是 Redwood Research 的首席科学家,专注于技术 AI 安全研究,以降低失控 AI 带来的风险。
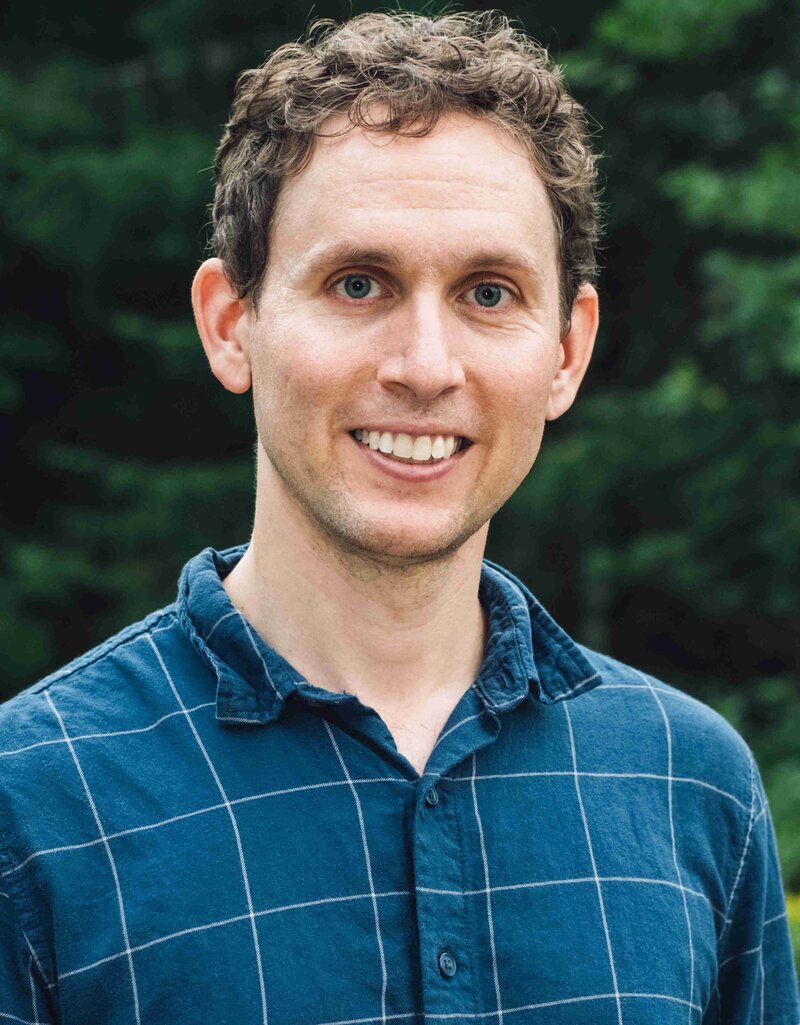
我是加州大学伯克利分校统计学与电气工程及计算机科学系的助理教授,同时也参与 BAIR 和 CLIMB 的工作。我还创立并担任 Transluce 的首席执行官。Transluce 是一家非营利研究实验室,致力于开发开放、可扩展的技术,帮助人们理解前沿 AI 系统。
I'm a research scientist at the UK AI Security Institute, working on AI control red teaming and model organisms of misalignment. I was previously a postdoc with Sam Bowman at NYU, did MATS with Owain Evans, and mentored for the MATS, SPAR and Pivotal fellowships. I got my PhD at the University of Edinburgh, supervised by Iain Murray.
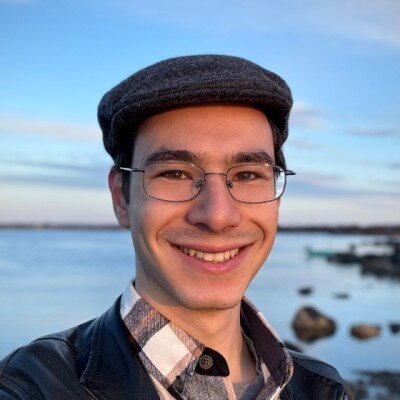
Stephen 目前在 Anthropic 担任研究员,研究如何对齐和控制超级智能。此前,他曾在 OpenAI 任研究员,也曾在卡内基梅隆大学(CMU)与 Tuomas Sandholm 合作进行博士后研究。他在加州大学尔湾分校获得计算机科学博士学位,导师是 Pierre Baldi。博士期间,他还曾在 Intel Labs 和 DeepMind 实习,担任研究科学家。更早之前,他于 2017 年获得亚利桑那州立大学数学与经济学学士学位。他感兴趣的项目包括:
- 与编码智能体控制和监控相关的研究
- 面向智能体对齐的可扩展监督
- 密谋行为的评估与缓解
- 用于构建稳健监控器和奖励模型的对抗训练
- 智能体中的奖励钻空子与欺骗行为
Gabriel works with RAND on hands-on projects to build and test prototypes of secure compute infrastructure. He focuses on how to secure the most sensitive AI data centers against the most sophisticated current and future threats. Gabriel has also worked on hardware-enabled governance mechanisms (HEMs, at the intersection of GPU export control and hardware security) and on technical verification of agreements on the development and use of AI systems. He holds a master's degree in computer science and is pursuing a PhD in AI.

Kyle 在 Anthropic 从事模型福祉研究。此前,他共同创立了 Eleos AI Research、Telis Bioscience 和 Alvea。
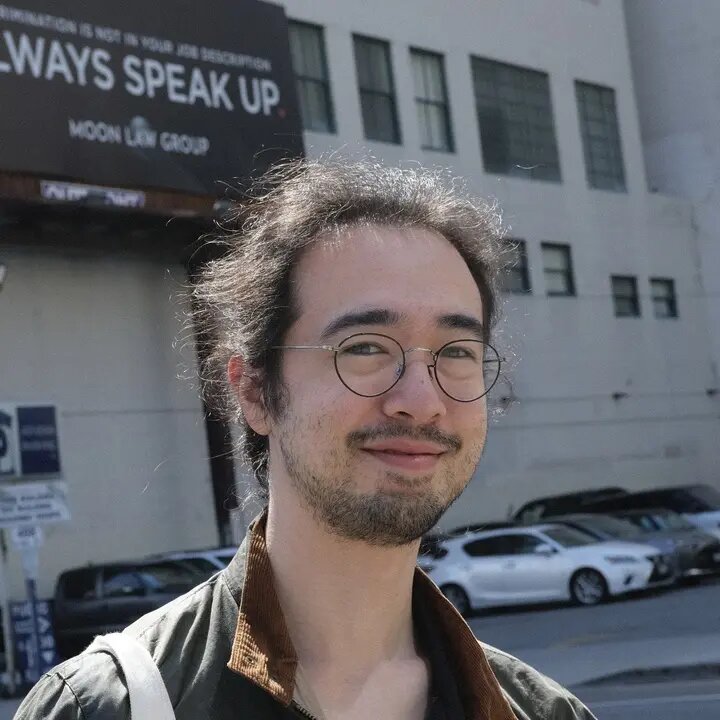
Julian leads the diffuse control team at Redwood.
Alex 是 Anthropic 的研究员,关注如何以有原则的方法,让模型形成与安全相关的结构。例如,他研究通过梯度路由将学习更新定位到模型的特定部分,以及通过蒸馏实现稳健的遗忘。
此前,Alex 曾在 Riot Games AI 和 Amazon 从事强化学习应用研究。他在北卡罗来纳州立大学获得统计学博士学位,导师是 Eric Laber。
Lee Sharkey is a Principal Investigator at [Goodfire](https://www.goodfire.ai/).
His team has focused on improved interpretability methods, including parameter decomposition methods such as [Attribution-based Parameter Decomposition](https://arxiv.org/abs/2501.14926) and [Stochastic Parameter Decomposition](https://arxiv.org/abs/2506.20790) and [adVersarial Parameter Decomposition](https://www.goodfire.ai/research/interpreting-lm-parameters#).
Previously, Lee was Chief Strategy Officer and cofounder of [Apollo Research](https://www.apolloresearch.ai/), and a Research Engineer at Conjecture, where he worked on [sparse autoencoders as a solution to representational superposition](https://www.alignmentforum.org/posts/z6QQJbtpkEAX3Aojj/interim-research-report-taking-features-out-of-superposition).